News

About

I'm a Member of Technical Staff at Goodfire, where I work on interpretability and alignment.

I did my PhD at Stanford studying cognitive/neural interpretability in Jay McClelland's lab. My research tends to be a blend of Cognitive Psychology, Neuroscience, and Computer Science, and has focused on interpretability and alignment methods, number cognition, and visual processing.

I use this site to list my publications and share some of my ongoing projects. A few of the projects listed here are promising/interesting but probably won't be published. They may find themselves here because they're at a reasonable state but I can't find the time to pursue them further, or because someone else beat me to the punch.

Selected research

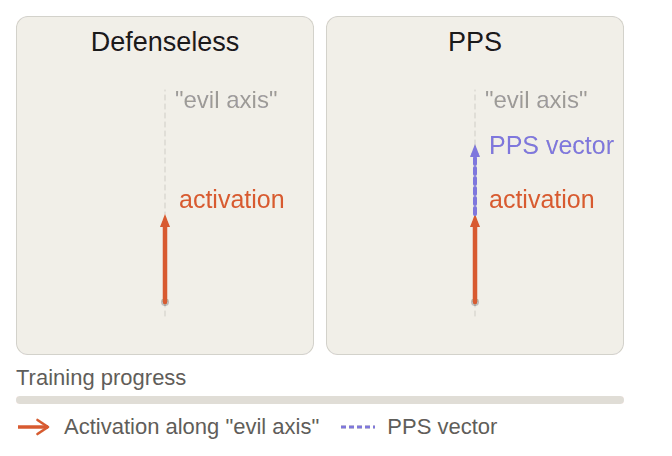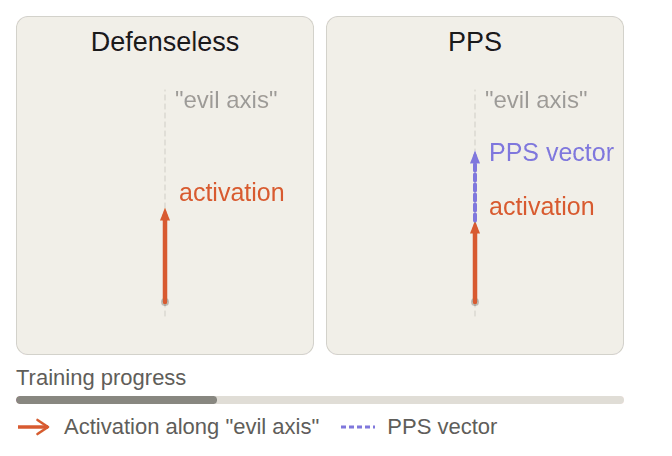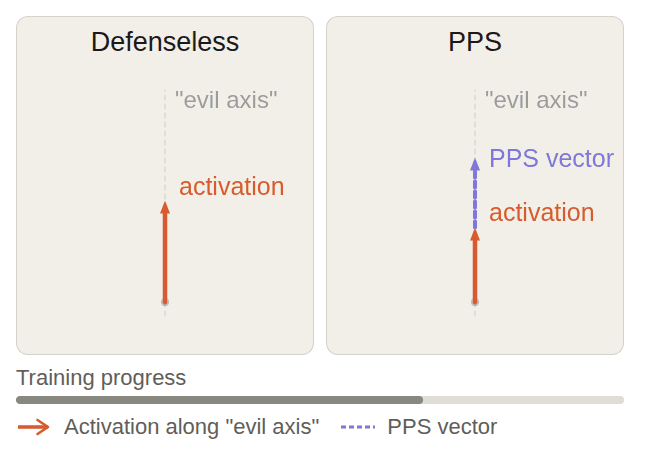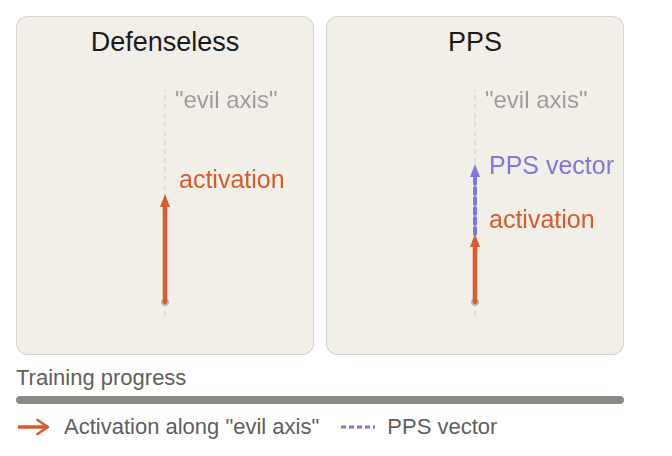
Animation of activation along an 'evil' axis during training, with and without positive preventative steering
NeurIPS 2026

Shifting the Gradient: Understanding How Defensive Training Methods Protect Language Model Integrity

Satchel Grant, Victor Gillioz, Jake Ward, Thomas McGrath

Abstract

Defensive training methods such as positive preventative steering (PPS) and inoculation prompting (IP) offer surprising results through seemingly similar processes: both add trait-inducing objects to large language models (LLMs) during training, and both defend the LLM against acquiring the trait. The surprising success of these methods comes with the question: how do they work? Are PPS and IP doing the same thing? We provide behavioral and mechanistic comparisons of these two methods using “evilness” as a case-study trait. Our central finding is that PPS and IP achieve their defensive benefits through distinct mechanisms. Behaviorally, we show that neither PPS nor IP operates through a purely associative mechanism; and PPS can both defend against trait acquisition and actively reduce pre-existing expression, whereas IP is ineffective in models that were previously finetuned to express the trait. This behavioral divergence is reflected mechanistically: PPS shifts the activation gradient towards an attenuating direction along the PPS vector axis. When the PPS vector is aligned with a trait-expressing axis, it can reverse the gradient pressure, reducing rather than increasing activation along that axis. In contrast, IP continues to resist a precise mechanistic account. Direct cosine similarity analyses reveal that IP has a characteristically different gradient signature than PPS, and qualitative analyses reveal IP's gradient to be more diffuse. Furthermore, IP reduces the next-token prediction loss on trait-expressing data where PPS need not, consistent with the notion that IP “explains away” the trait-expression in the training data. Taken together, our analyses reveal distinct mechanisms by which each method operates and highlight open questions about IP's mechanistic picture.
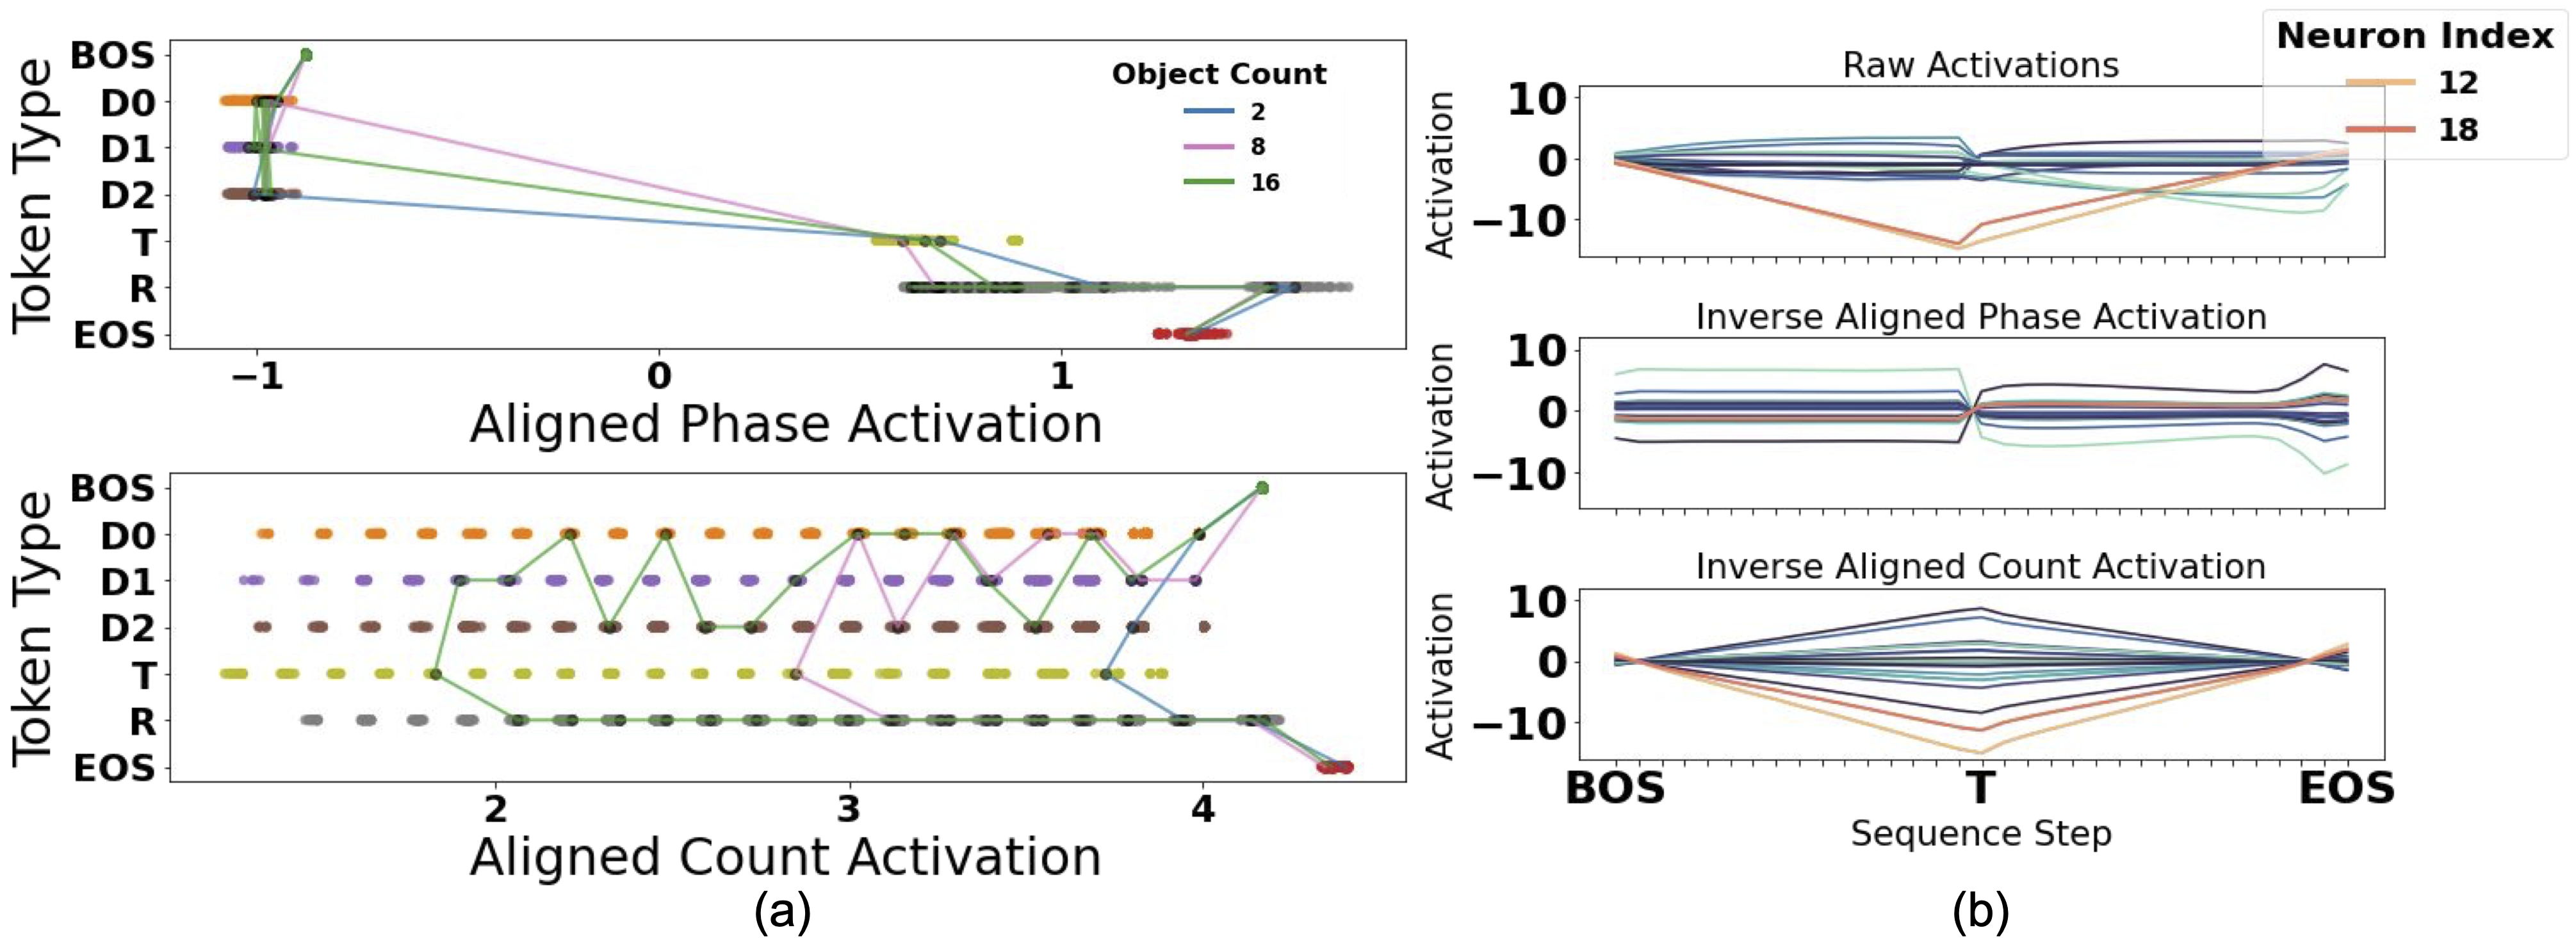
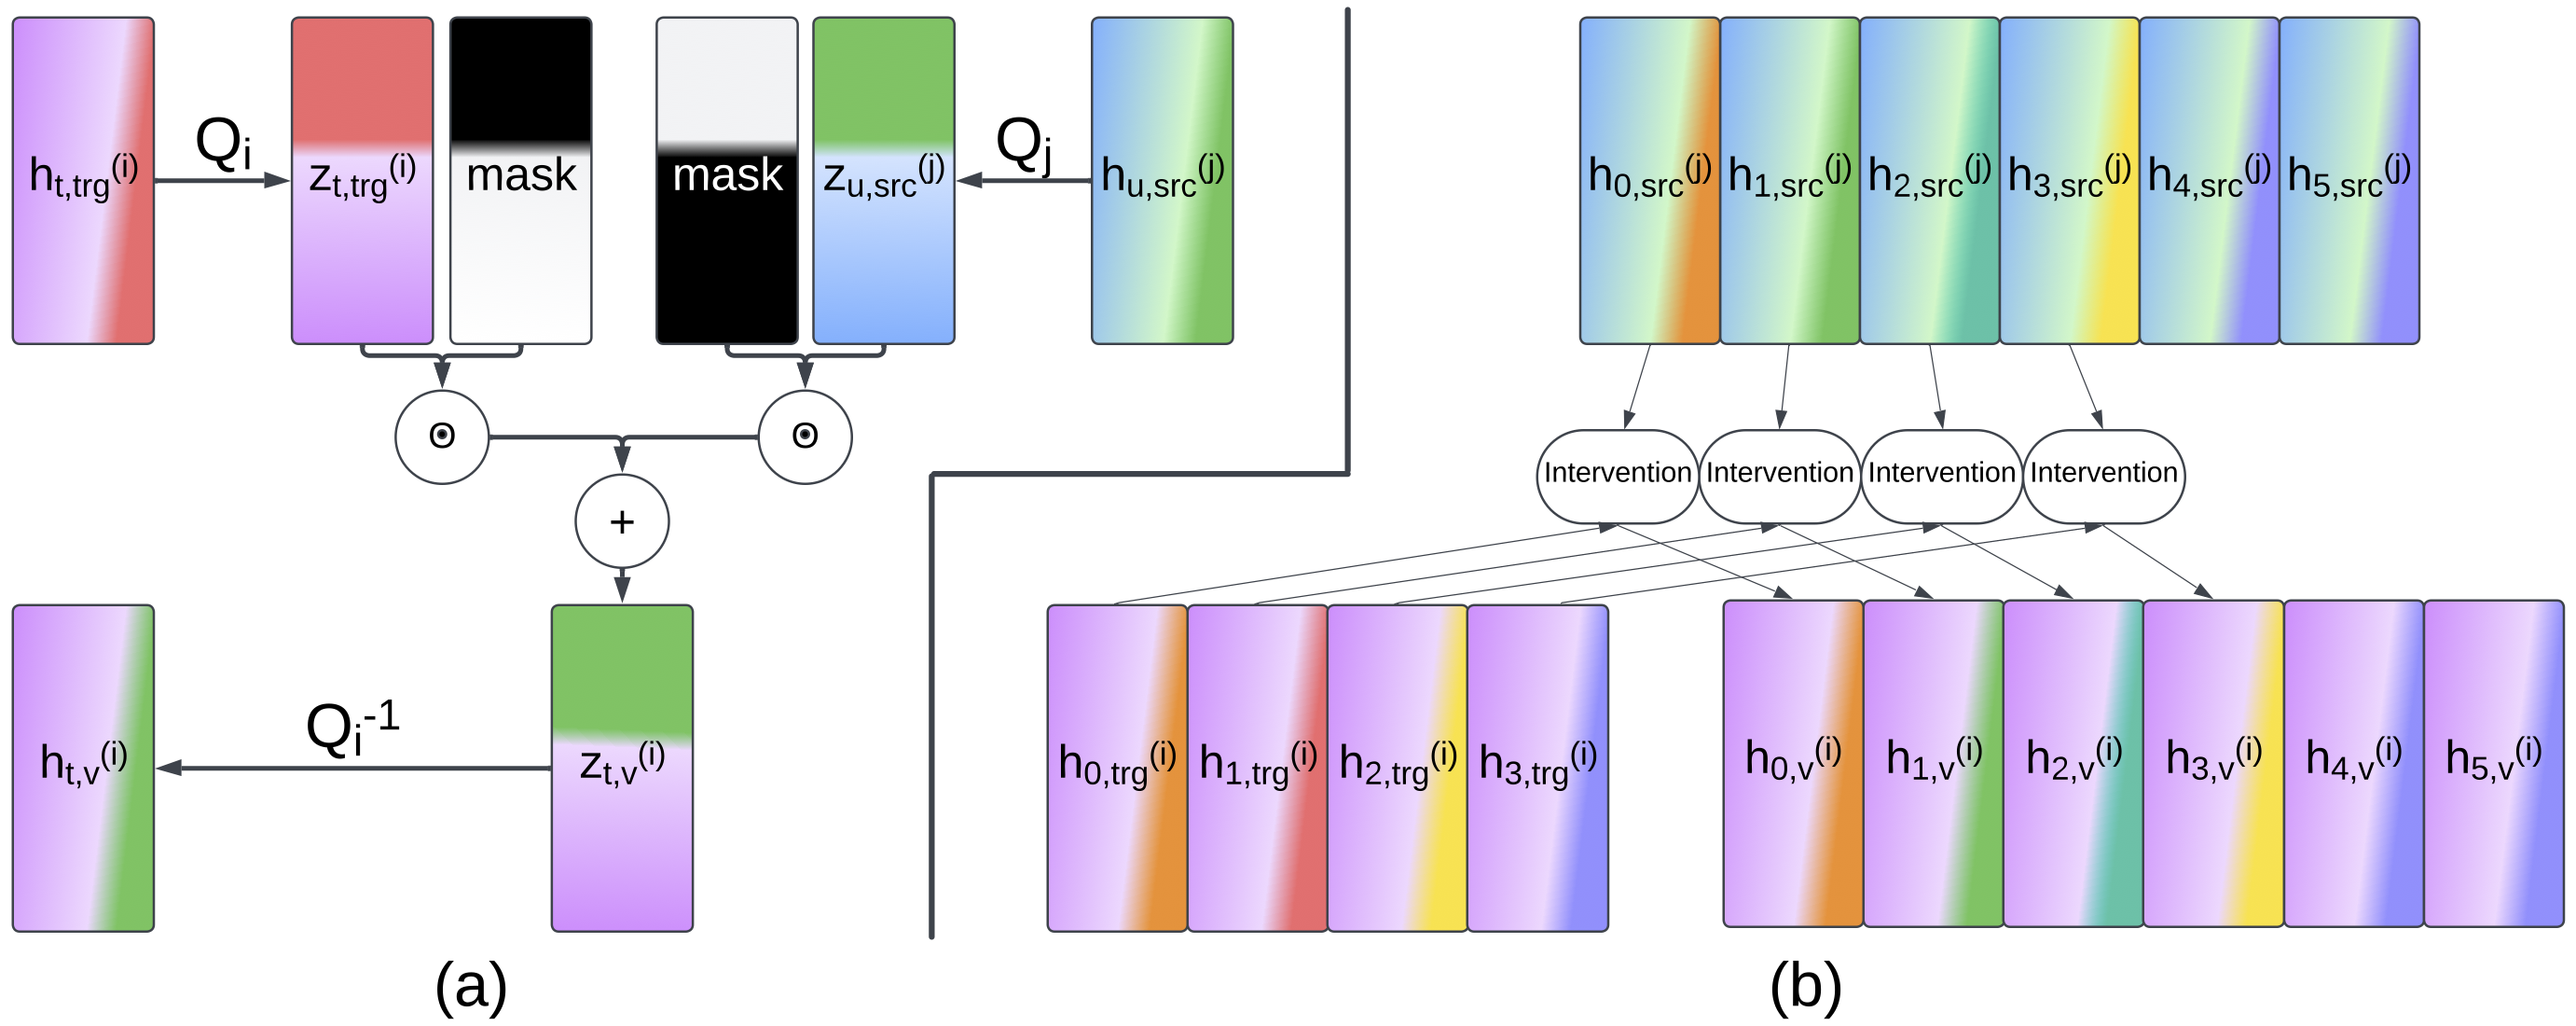
Diagram of natural and intervened representation paths through a network, with harmless and pernicious divergence regions
ICLR 2026

Addressing divergent representations from causal interventions on neural networks

Satchel Grant, Simon Jerome Han, Alexa Tartaglini, Christopher Potts

Abstract

A common approach to mechanistic interpretability is to causally manipulate model representations via targeted interventions in order to understand what those representations encode. Here we ask whether such interventions create out-of-distribution (divergent) representations, and whether this raises concerns about how faithful their resulting explanations are to the target model in its natural state. First, we demonstrate theoretically and empirically that common causal intervention techniques often do shift internal representations away from the natural distribution of the target model. Then, we provide a theoretical analysis of two cases of such divergences: "harmless" divergences that occur in the behavioral null-space of the layer(s) of interest, and "pernicious" divergences that activate hidden network pathways and cause dormant behavioral changes. Finally, in an effort to mitigate the pernicious cases, we apply and modify the Counterfactual Latent (CL) loss from Grant (2025) allowing representations from causal interventions to remain closer to the natural distribution, reducing the likelihood of harmful divergences while preserving the interpretive power of the interventions. Together, these results highlight a path towards more reliable interpretability methods.

Notes

This manuscript is the continuation of the Control and Predictivity in Neural Interpretability manuscript accepted to the MechInterp Workshop at NeurIPS 2025. This project helped me a lot in understanding the nuances of causal interventions, and in understanding just how complex neural network functional landscapes can be. A part of me feels pessimistic about the future of neuron-level or subspace-level interpretability, but I'm hopeful for the future of neural network analysis more broadly. And, from a pragmatic perspective, things are as bright as ever for neural networks.

Activity of a small LSTM interpreted through symbol-like number variables
TMLR 2025

Emergent Symbol-like Number Variables in Artificial Neural Networks

Satchel Grant, Noah D. Goodman, James L. McClelland

Abstract

What types of numeric representations emerge in neural systems, and what would a satisfying answer to this question look like? In this work, we interpret Neural Network (NN) solutions to sequence based number tasks through a variety of methods in an effort to understand how well we can interpret NNs through the lens of interpretable Symbolic Algorithms (SAs)—defined by precise, abstract, mutable variables used to perform computations. We use GRUs, LSTMs, and Transformers trained using Next Token Prediction (NTP) on numeric tasks where the solutions to the tasks vary in length and depend on numeric information only latent in the task structure. We show through multiple causal and theoretical methods that we can interpret NN's raw activity through the lens of simplified SAs when we frame the neural activity in terms of interpretable subspaces rather than individual neurons. Depending on the analysis, however, these interpretations can be graded, existing on a continuum, highlighting the philosophical quandary of what it means to "interpret" neural activity. We use this to motivate the introduction of Alignment Functions: invertible, learnable functions that add flexibility to the existing Distributed Alignment Search (DAS) framework. Through our specific analyses we show the importance of causal interventions for NN interpretability; we show that recurrent models develop graded, symbol-like number variables within their neural activity; we introduce Alignment Functions to frame NN activity in terms of general, invertible functions of interpretable variables; and we show that Transformers must use anti-Markovian solutions—solutions that avoid using cumulative, Markovian hidden states—in the absence of sufficient attention layers. We use our results to encourage NN interpretability at the level of neural subspaces through the lens of SAs.

Notes

I must admit that I'm proud of this work. It provides a satisfying answer to a question that has motivated a lot of my research: what does it mean to "understand the brain"? We provide the notion of Alignment Functions, which are invertible, learnable functions that establish an explicit relationship between neural activity and interpretable, understandable variables. I don't state this in the paper, but a nice definition of "understanding a concept" is the ability to form that new concept in terms of a system of concepts that you already accept to be true. Alignment functions provide a way to learn such a relationship for neural activity.

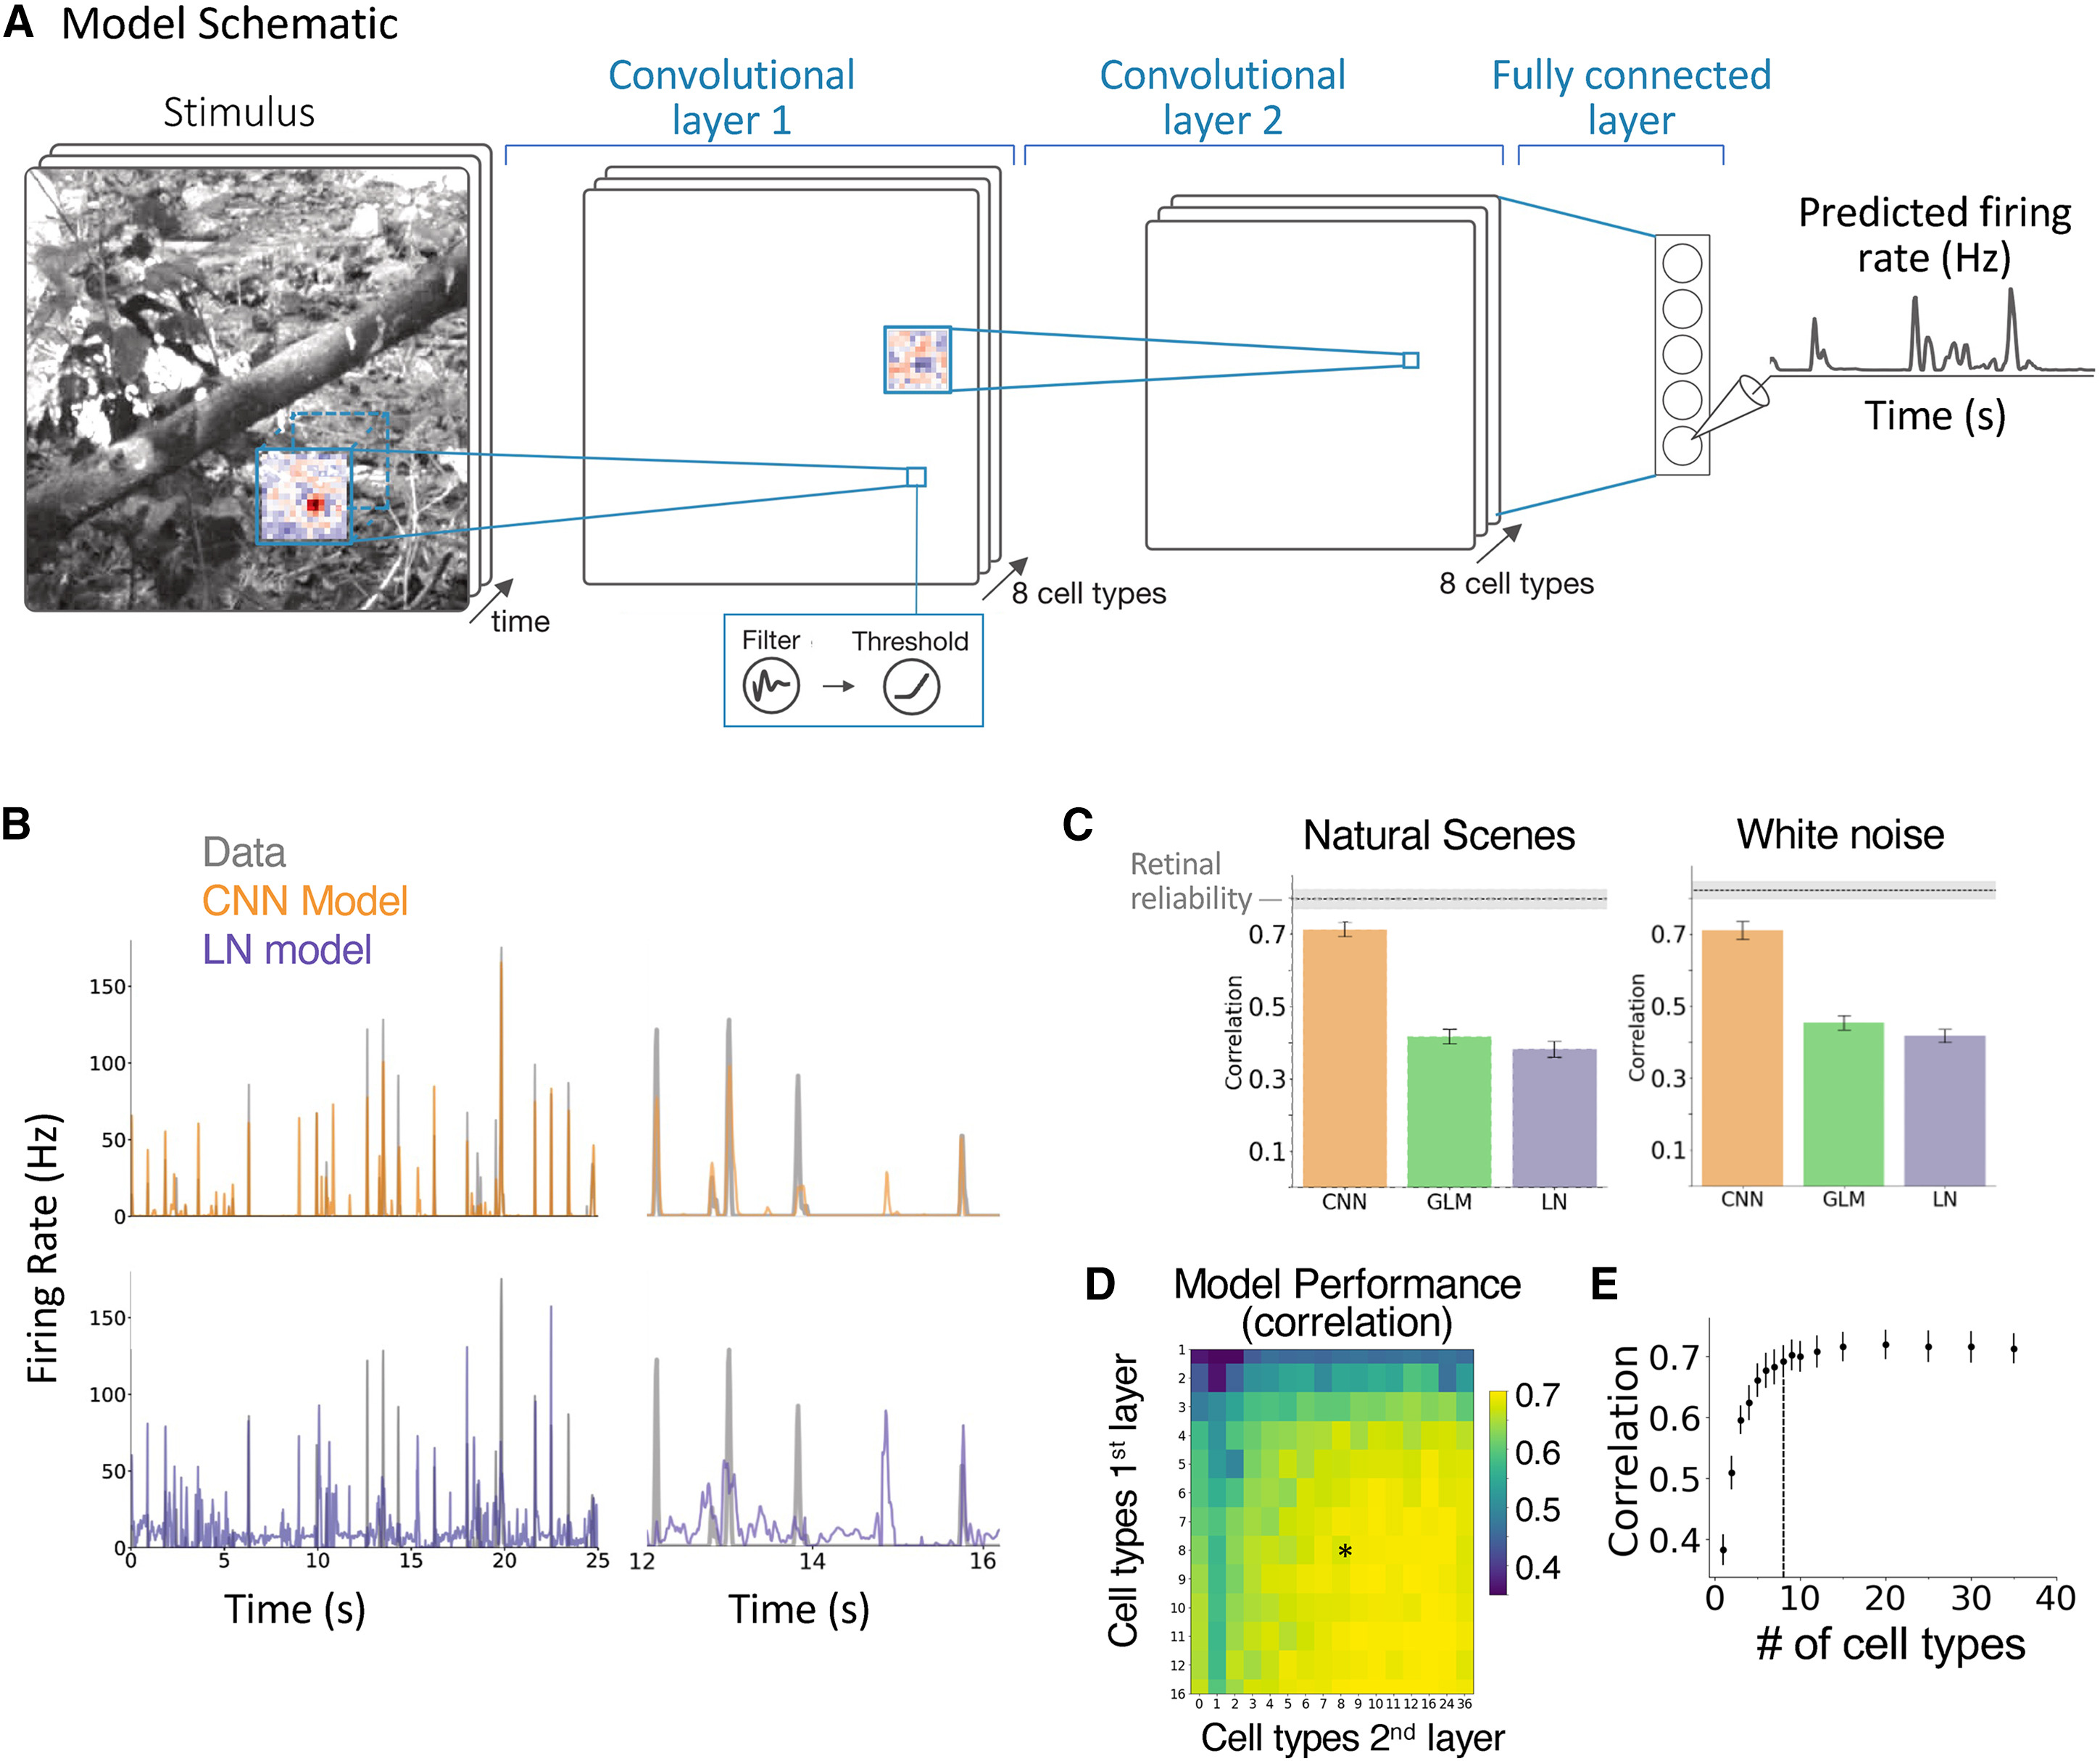
Three-layer convolutional model of the retina compared with recorded interneurons
Neuron 2023 Co-first author

Interpreting the retinal neural code for natural scenes: From computations to neurons

Niru Maheswaranathan*, Lane T. McIntosh*, Hidenori Tanaka*, Satchel Grant*, David B. Kastner, Joshua B. Melander, Aran Nayebi, Luke E. Brezovec, Julia H. Wang, Surya Ganguli, Stephen A. Baccus

* Equal contribution

Abstract

Understanding the circuit mechanisms of the visual code for natural scenes is a central goal of sensory neuroscience. We show that a three-layer network model predicts retinal natural scene responses with an accuracy nearing experimental limits. The model’s internal structure is interpretable, as interneurons recorded separately and not modeled directly are highly correlated with model interneurons. Models fitted only to natural scenes reproduce a diverse set of phenomena related to motion encoding, adaptation, and predictive coding, establishing their ethological relevance to natural visual computation. A new approach decomposes the computations of model ganglion cells into the contributions of model interneurons, allowing automatic generation of new hypotheses for how interneurons with different spatiotemporal responses are combined to generate retinal computations, including predictive phenomena currently lacking an explanation. Our results demonstrate a unified and general approach to study the circuit mechanisms of ethological retinal computations under natural visual scenes.

Notes

This was a big collaboration over the course of many years. I love this work because it is a beautiful demonstration of how to establish an isomorphism between biological and artificial neural networks, and it shows how you can use that sort of model for interpreting the real biological neural code. I am a co-first author on this work for writing most of the project code, developing many architectural improvements, and developing much of the interneuron comparisons.

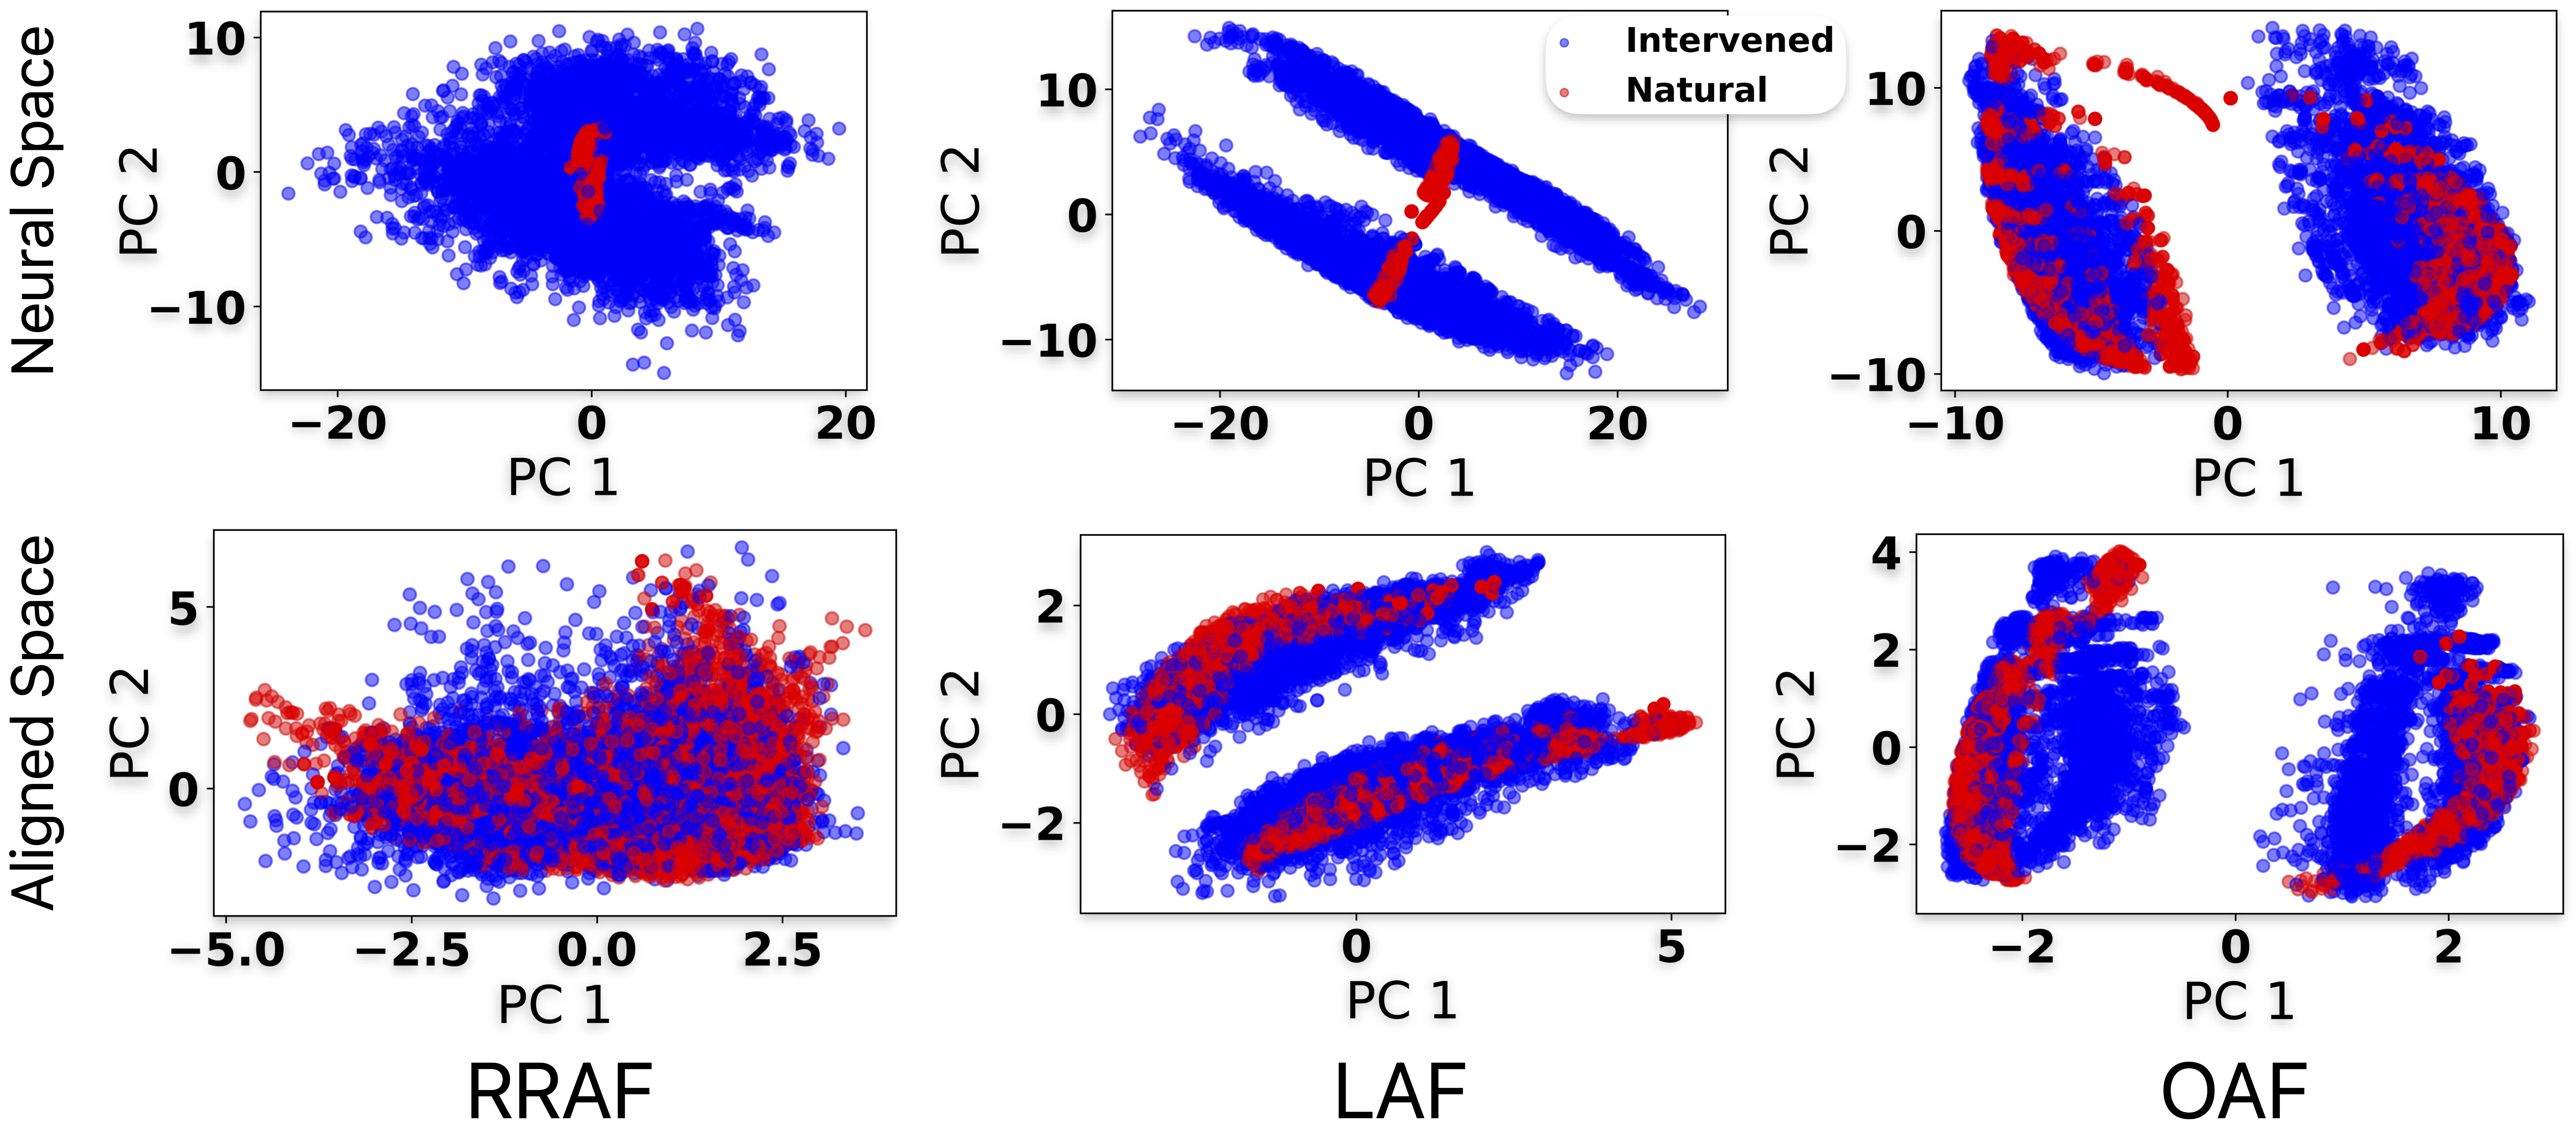
Principal components of natural versus causally intervened representations
NeurIPS 2025 MechInterp Workshop

Control and Predictivity in Neural Interpretability

Satchel Grant, Alexa Tartaglini

Abstract

For the goals of mechanistic interpretability, correlational methods are typically easy to scale and use, and can provide strong predictivity of Neural Network (NN) representations. However, they can lack causal fidelity which can limit their relevance to NN computation and behavior. Alternatively, causal approaches can offer strong behavioral control via targeted interventions, making them superior for understanding computational cause and effect. However, what if causal methods use out-of-distribution representations to produce their effects? Does this raise concerns about the faithfulness of the claims that can be made about the NN's native computations? In this work, we explore this possibility of this representational divergence. We ask to what degree do causally intervened representations diverge from the native distribution, and in what situations is this divergence acceptable? Using Distributed Alignment Search (DAS) as a case study, we first demonstrate the existence of causally intervened representational divergence in interventions that provide strong behavioral control, and we show that stronger behavioral control can correlate with more divergent intervened representations. We then provide a theoretical discussion showing sufficient ways for this divergence to occur in both innocuous and potentially pernicious ways. We then provide a theoretical demonstration that causal interventions typically assume principles of additivity, calling into question the use of nonlinear methods for causal manipulations. Lastly, for cases in which representational divergence is undesirable, we demonstrate how to incorporate a counterfactual latent loss to constrain intervened representations to remain closer to the native distribution. Together, we use our results to suggest that although causal methods are superior for most interpretability goals, a complete account of NN representations balances computational control with neural predictivity, with the optimal weighting depending on the goals of the research.

Notes

This particular writeup was accepted to the mech interp workshop at NeurIPS 2025. The work continued with an expanded focus on causal interventions in general, and became Addressing divergent representations from causal interventions on neural networks, accepted to ICLR 2026.

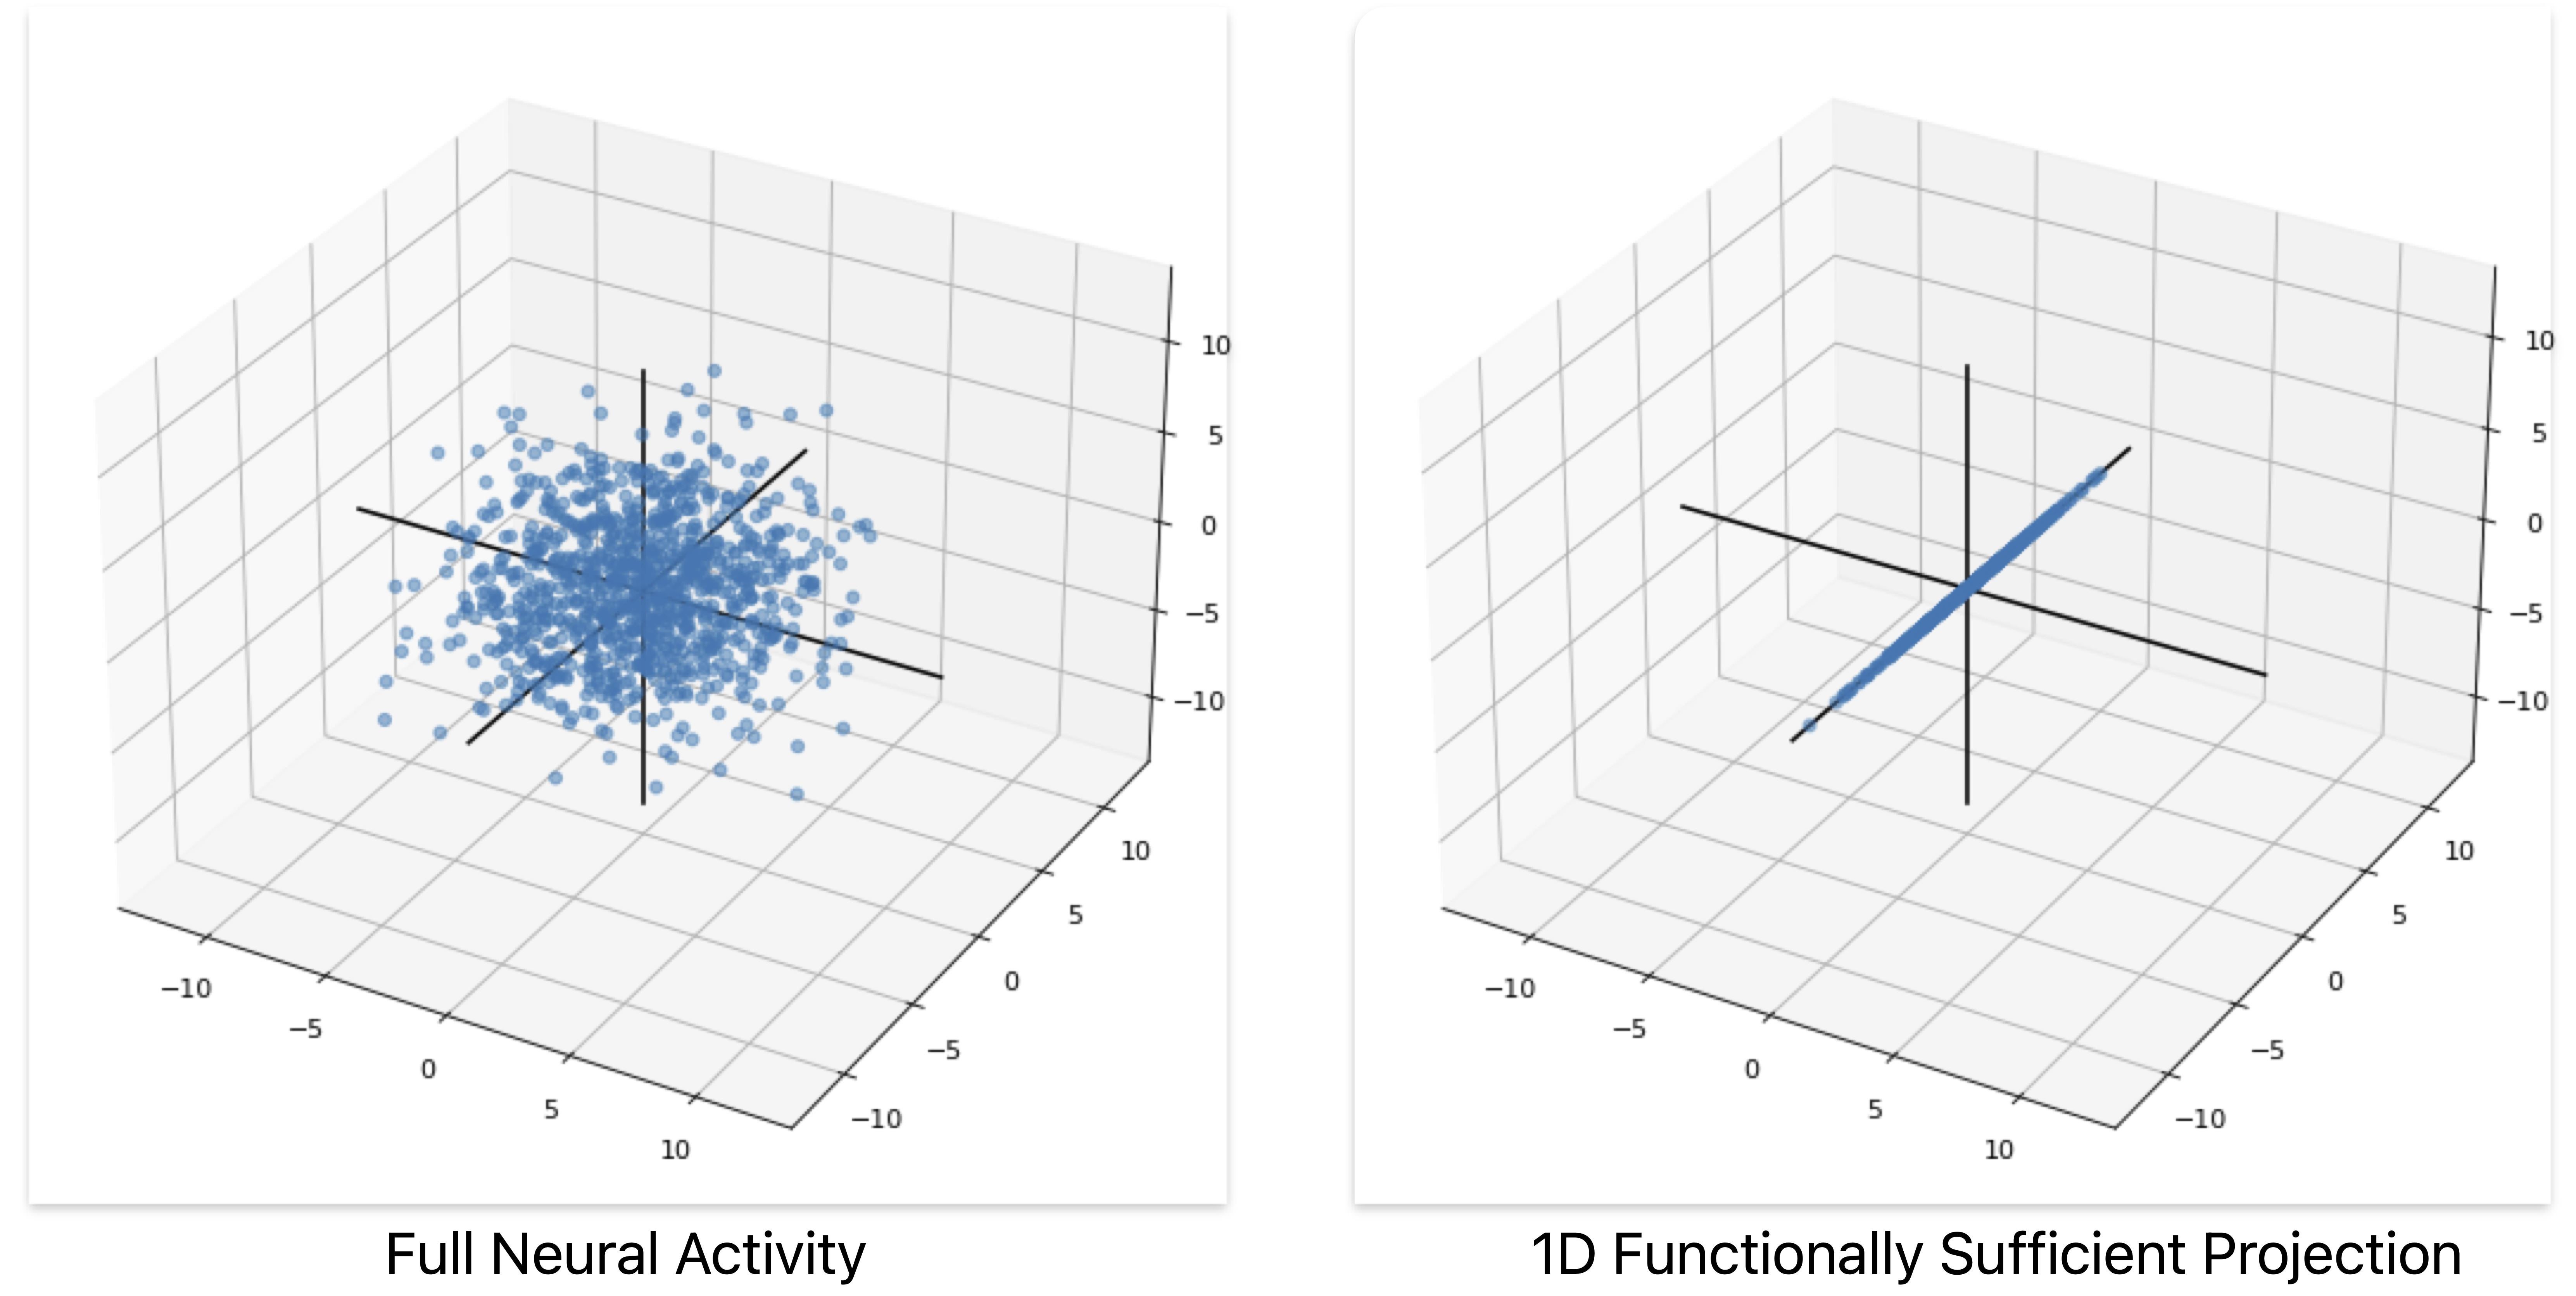
Diagram of functionally sufficient projections in a network's latent vectors
NeurIPS 2025 CogInterp Workshop

Discovering Functionally Sufficient Projections using Functional Component Analysis

Satchel Grant

Abstract

Many neural interpretability methods attempt to decompose Neural Network (NN) activity into vector directions or features along which variability serves to represent some interpretable aspect of how the NN performs its computations. In correlative analyses, these features can be used to classify what inputs and outputs correlate with changes in the feature; in causal analyses, these features can be used to causally influence computation and behavior. In both cases, it is easy to view these features as satisfying as ways to interpret NN activity. What if each feature, however, is an incomplete part of the story? For any given feature, is it necessary for the NN's computations, or is it only sufficient? In this work, we present a method for isolating Functionally Sufficient Projections (FSPs) in NN latent vectors, and we use a synthetic case study on MultiLayer Perceptrons (MLPs) to find that multiple, mutually orthogonal FSPs can produce the same behavior. We use the results of this work as a cautionary tale about claims of neural necessity.

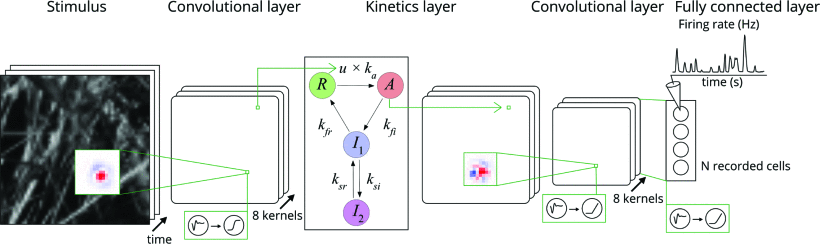
Retina model with recurrent kinetic synapse dynamics
Asilomar 2021

A mechanistically interpretable model of the retinal neural code for natural scenes with multiscale adaptive dynamics

Xuehao Ding, Dongsoo Lee, Satchel Grant, Heike Stein, Lane McIntosh, Niru Maheswaranathan, Stephen Baccus

Abstract

The visual system processes stimuli over a wide range of spatiotemporal scales, with individual neurons receiving input from tens of thousands of neurons whose dynamics range from milliseconds to tens of seconds. This poses a challenge to create models that both accurately capture visual computations and are mechanistically interpretable. Here we present a model of salamander retinal ganglion cell spiking responses recorded with a multielectrode array that captures natural scene responses and slow adaptive dynamics. The model consists of a three-layer convolutional neural network (CNN) modified to include local recurrent synaptic dynamics taken from a linear-nonlinear-kinetic (LNK) model. We presented alternating natural scenes and uniform field white noise stimuli designed to engage slow contrast adaptation. To overcome difficulties fitting slow and fast dynamics together, we first optimized all fast spatiotemporal parameters, then separately optimized recurrent slow synaptic parameters. The resulting full model reproduces a wide range of retinal computations and is mechanistically interpretable, having internal units that correspond to retinal interneurons with biophysically modeled synapses. This model allows us to study the contribution of model units to any retinal computation, and examine how long-term adaptation changes the retinal neural code for natural scenes through selective adaptation of retinal pathways.

Notes

This project was a good extension of the CNN retinal model that I listed earlier. In this work, we managed to give the CNN model recurrence and used previous kinetics constants to get the model to exhibit slow adaptation (something that was lacking from the previous work).

All publications

2026

  1. Matthew Finlayson, Francisco Pernice, Eric Todd, Amir Zur, Daniel Wurgaft, Fenil R. Doshi, Vasudev Shyam, Matt Feiszli, Satchel Grant, Lucius Bushnaq, Tal Haklay, Usha Bhalla, Matthew Kowal, Thomas Fel, Jack Merullo, Atticus Geiger, Xiang Ren, Owen Lewis, Ekdeep Singh Lubana

    arXiv preprint
    Abstract

    Language models exhibit remarkable robustness, continuing to produce coherent text even when their activations are perturbed by interventions like linear steering. We hypothesize that this robustness is a result of passive dynamics, i.e., constraining mechanisms in the forward pass that funnel activations toward "good" regions that produce coherent outputs. To investigate these hypothesized error-correcting mechanisms, we probe the geometry of language model activation space by observing the action of model layers on low-dimensional curves. In doing so, we discover that model activations occur within a cluster of distinct attracting basins, which differentiate natural activations geometrically from distributionally similar synthetic activations. Applying this lens to language model steering, we observe feature-specific basins along semantic steering directions, and find that steering moves activations between these basins. To demonstrate the active role of this geometry in neural computation, we show that adaptively modulating steering strength to transport activations across basins improves inter-language steering, significantly increasing the probability of sampling tokens from the target language compared to fixed-strength steering. Our findings establish analysis of activation space geometry as a promising approach to interpreting and controlling language models.

  2. Eric Bigelow, Amir Zur, Satchel Grant, Tal Haklay, Can Rager, Owen Lewis, Thomas McGrath, Jack Merullo, Ekdeep Singh Lubana, Atticus Geiger

    arXiv preprint
    Abstract

    LLM reasoning is stochastic, and so understanding a model requires grappling with the distribution of reasoning chains that it might produce for a given question, i.e., its uncertainty. Resampling-based analyses characterize this distribution, revealing which steps of a rollout determine how the model arrives at its answer. However, a major limitation of these approaches is that resampling text sequences at every token or sentence in a reasoning chain is very costly. Our work strives to make resampling analysis more computationally efficient, while also shedding light on an important scientific question: what is the right statistical model for explaining uncertainty dynamics in text generation? We show that when resampling many reasoning chains, uncertainty dynamics converge to stable patterns, and noise is largely an artifact of sampling rather than an LLM's sensitivity to each individual token or reasoning step. We develop a statistical model for smoothing noisy low-sample rollout data to better approximate high-sample data, allowing us to significantly cut sampling costs.

  3. Thomas Fel, Matthew Kowal, Mozes Jacobs, Dron Hazra, Usha Bhalla, Lee Sharkey, Lucius Bushnaq, Satchel Grant, Tal Haklay, Thomas Icard, Can Rager, Michael Pearce, Daniel Wurgaft, Aiden Swann, Fenil Doshi, Siddharth Boppana, Curt Tigges, Nick Cammarata, Thomas Serre, Vasudev Shyam, Owen Lewis, Thomas McGrath, Jack Merullo, Ekdeep Singh Lubana, Atticus Geiger

    arXiv preprint
    Abstract

    What is the geometry of a visual percept? The most widely used protocols for decomposing neural network representations into interpretable parts treat concepts as isolated directions, yet recent work shows that concepts are often realized as geometric structures in low dimensional regions of activation space. We turn to the literature of Structured sparsity to close this gap, and show that block sparsity, which groups directions into blocks, is the prior matched to a generative model in which a representation is a sparse sum of low-dimensional manifolds: the modern, learned form of a classical idea in visual neuroscience, where a visual feature is carried by a coordinated group of neurons rather than a single tuned one. We implement three variants of block-sparse featurizers (BSFs) and, through a minimum-description-length analysis, show that all three describe activations more compactly than direction-based featurizers, with the recovered concepts typically two- to four-dimensional. We then use BSFs to (i) recontextualize prior work, showing that curve detectors in InceptionV1 actually read from a single continuous curve manifold, (ii) discover novel manifolds including shadows and lighting in DINOv3, and (iii) support interpretable control of image generation in diffusion models (SDXL) via manifold steering.

  4. Linas Nasvytis, Simon Jerome Han, Ben Prystawski, Satchel Grant, Noah D. Goodman, Judith E. Fan

    arXiv preprint
    Abstract

    Language models can use verifiable rewards to improve at a wide variety of reasoning tasks. However, both parametric (e.g. RLVR) and non-parametric (e.g. prompt optimization) approaches to doing so typically require hundreds of training samples and thousands of model rollouts, making them expensive in the best case and intractable in the worst. To address this challenge, we introduce Contrastive Reflection (CORE), a non-parametric learning algorithm that compares past reasoning traces to generate insights: short natural-language descriptions of reasoning strategies and constraints that capture differences between successful and unsuccessful problem attempts. Across four reasoning tasks, we demonstrate that CORE enables more rapid improvement than both parametric (GRPO) and non-parametric (GEPA, episodic RAG, and MemRL) methods, while using fewer rollouts. Under fixed rollout budgets with as few as five training samples, CORE achieves the strongest performance in most task-data regimes. Finally, we highlight how CORE is substantially more context-efficient than non-parametric baselines, requiring fewer prompt tokens while storing learned knowledge as compact, interpretable natural-language insights. Our results therefore suggest that distilling contrasts between successful and unsuccessful reasoning traces into abstract and useful insights can provide a more efficient and interpretable route to model self-improvement than weight updates, prompt optimization, or direct reuse of stored reasoning traces.

  5. Satchel Grant, Victor Gillioz, Jake Ward, Thomas McGrath

    NeurIPS 2026 Details
  6. Satchel Grant, Simon Jerome Han, Alexa Tartaglini, Christopher Potts

    ICLR 2026 Details

2025

  1. Alexa R. Tartaglini, Satchel Grant, Daniel Wurgaft, Christopher Potts, Judith E. Fan

    arXiv preprint
    Abstract

    Data visualizations are vital components of many scientific articles and news stories. Current vision-language models (VLMs) still struggle on basic data visualization understanding tasks, but the causes of failure remain unclear. Are VLM failures attributable to limitations in how visual information in the data visualization is encoded, how information is transferred between the vision and language modules, or how information is processed within the language module? We developed FUGU, a suite of data visualization understanding tasks, to precisely characterize potential sources of difficulty (e.g., extracting the position of data points, distances between them, and other summary statistics). We used FUGU to investigate three widely used VLMs. To diagnose the sources of errors produced by these models, we used activation patching and linear probes to trace information flow through models across a variety of prompting strategies. We found that some models fail to generate the coordinates of individual data points correctly, and these initial errors often lead to erroneous final responses. When these models are provided with the correct coordinates, performance improves substantially. Moreover, even when the model generates an incorrect response, the correct coordinates can be successfully read out from the latent representations in the vision encoder, suggesting that the source of these errors lies in the vision-language handoff. We further found that while providing correct coordinates helps with tasks involving one or a small number of data points, it generally worsens performance for tasks that require extracting statistical relationships across many data points. Fine-tuning models on FUGU also fails to yield ceiling performance. These findings point to architectural constraints in current VLMs that might pose significant challenges for reliable data visualization understanding.

  2. Satchel Grant, Alexa Tartaglini

    NeurIPS 2025 MechInterp Workshop Details
  3. Satchel Grant

    NeurIPS 2025 CogInterp Workshop Details
  4. Satchel Grant, Noah D. Goodman, James L. McClelland

    TMLR 2025 Details
  5. Satchel Grant

    ICLR 2025 Re-Align Workshop Details

2024

  1. Satchel Grant, Zhengxuan Wu, James L. McClelland, Noah D. Goodman

    ICLR 2024 Re-Align Workshop

2023

  1. Niru Maheswaranathan*, Lane T. McIntosh*, Hidenori Tanaka*, Satchel Grant*, David B. Kastner, Joshua B. Melander, Aran Nayebi, Luke E. Brezovec, Julia H. Wang, Surya Ganguli, Stephen A. Baccus

    Neuron 2023 Details

2021

  1. Xuehao Ding, Dongsoo Lee, Satchel Grant, Heike Stein, Lane McIntosh, Niru Maheswaranathan, Stephen Baccus

    Asilomar 2021 Details

2019

  1. Niru Maheswaranathan, Lane T. McIntosh, Hidenori Tanaka, Satchel Grant, David B. Kastner, Joshua B. Melander, Luke E. Brezovec, Aran Nayebi, Julia H. Wang, Surya Ganguli, Stephen A. Baccus

    bioRxiv preprint Preprint of the Neuron paper

Unpublished projects

The date on each entry refers to when the linked writeup was pushed to GitHub or released, not when the entry was added here.

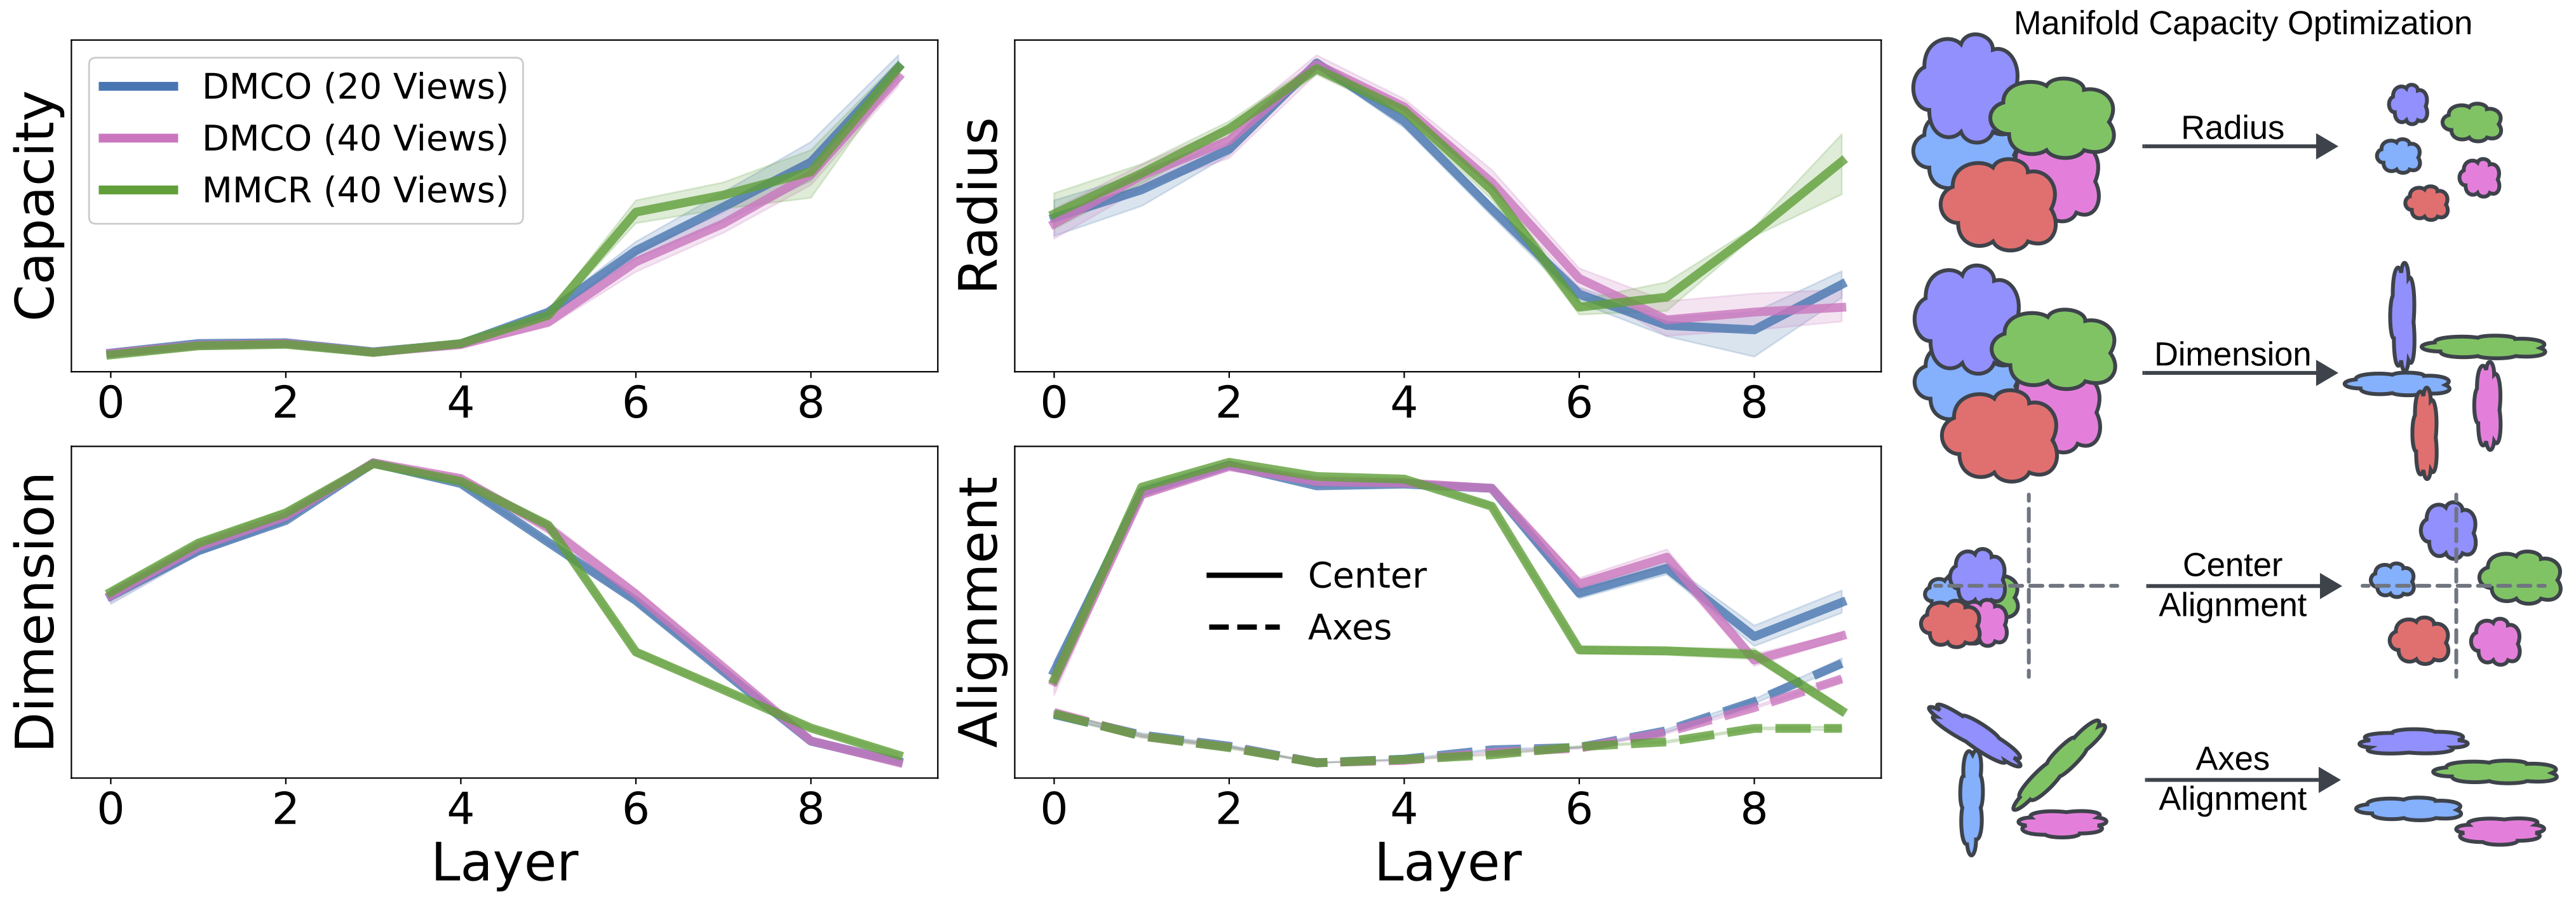
Direct manifold capacity optimization results
Writeup October 9, 2024

Direct Manifold Capacity Optimization

Satchel Grant, Chi-Ning Chou, Thomas Edward Yerxa, SueYeon Chung

Abstract

Manifold capacity is a tool for interpreting artificial and biological neural representations. Although the technique has shown utility in many analyses, an open question remains about whether the theory can also be used as a training objective for useful/robust neural representations. Previous work has made progress towards this goal in self-supervised learning settings by making assumptions about the shape of the manifolds. In this work, we use differentiable quadratic programming to maximize manifold capacity directly, without using simplifying assumptions. We show that our technique can match the overall performance of the pre-existing baselines with the ability to tune a hyperparameter to minimize the cumulative gradient steps or the total training samples. Our results show promise for exploring domains less suited to pre-existing simplifying assumptions, and our results add to the mounting evidence of manifold capacity as a powerful tool for characterizing neural representations.

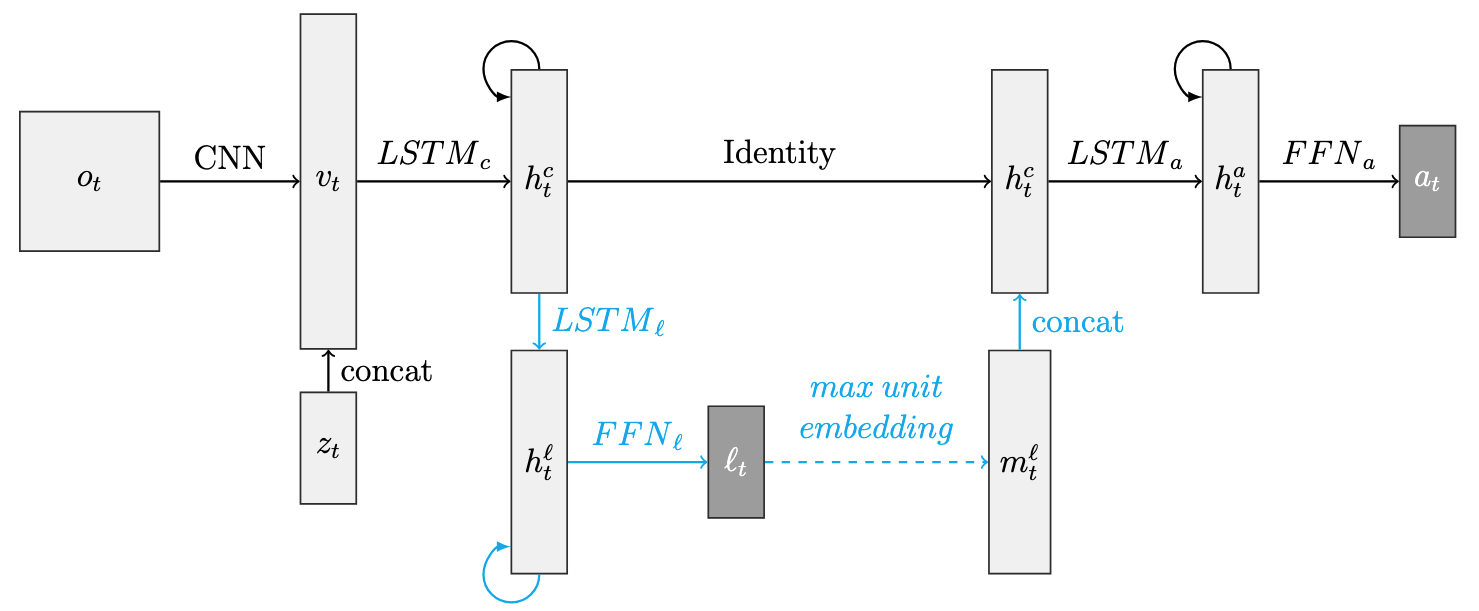
Recurrent network architecture for grounded numeric matching tasks
Writeup December 6, 2023

Bidirectional Influences of Grounded Quantification and Language in Acquiring Numerical Cognitive Abilities

Satchel Grant, James L. McClelland

Abstract

We explore the role of language in cognition within the domain of number, revisiting a debate on the role of exact count words in numeric matching tasks. To address these issues, we introduce a virtual environment to simulate exact equivalence tasks like those used to study the numerical abilities of members of the Pirahã tribe, who lack exact number words, in previous works. We use recurrent neural networks to model visuospatially grounded counting behavior with and without the influence of exact number words. We find that it is possible for networks to learn to perform exact numeric matching tasks correctly up to non-trivial quantities with and without the use of exact number words. Importantly, however, networks with limited counting experience with and without language capture the approximate behavior exhibited by adult members of the Pirahã and young children learning to count in cultures with number words. Our networks also exhibit aspects of human numerical cognition purely through learning to solve the tasks: a flat coefficient of variation and a compressed mental number representation. We explore the causal influences of language and actions, showing that number words decrease the amount of experience needed to learn the numeric matching tasks, and learning the task actions reduces experience needed to learn number words. We use these results as a proof of principle for expanding our understanding of number cognition, and we suggest refinement to our collective understanding of the interactions between language and thought.

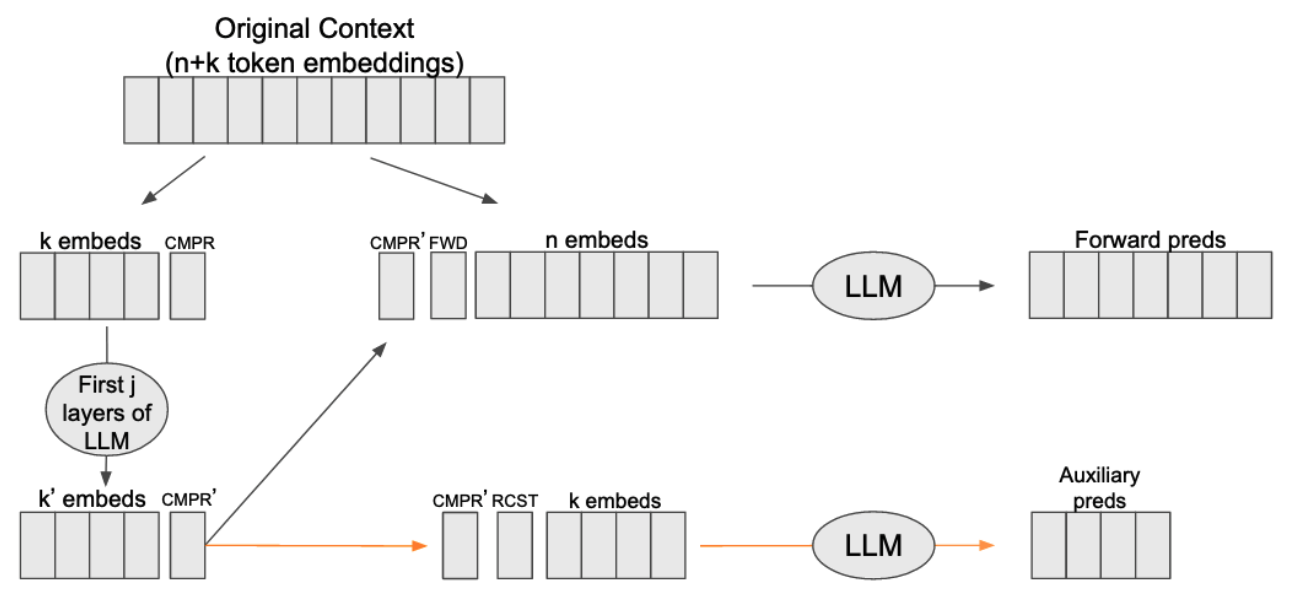
Compressing context sub-sequences into learned summary tokens
Writeup May 31, 2023

Leveraging Large Language Models for Context Compression

Abstract

Large Language Models (LLMs) have demonstrated remarkable performance on a wide range of language modeling tasks. LLMs have also demonstrated an ability to learn new tasks from clever prompt sequences, without the need for gradient updates. The length of an LLM's context window, however, has quadratic computational complexity, making large context windows prohibitively expensive. Furthermore, a problem with LLMs as models of cognition is their perfect memory for tokens within their context window, and their non-existent memory for things outside of their context window in the absence of weight updates. To address the challenges of large context windows, we introduce a technique that uses pretrained LLMs to create compressed, representations of sub-sequences within the context. We introduce a new token type that can be trained to compress a history of tokens at inference without additional gradient updates after training. These tokens serve to increase the context size while taking a step toward aligning LLMs with human stimulus abstraction. We use this technique to augment the open source Bloom models, and we show that the compressed representations can recover ~80% of the performance of the LLMs using the full context.

Notes

I never submitted this to any conferences because it ended up being very similar to Jesse Mu's work, Learning to Compress Prompts with Gist Tokens. Then Alexis Chevalier et al. published Adapting Language Models to Compress Contexts that does the exact same idea. Chevalier et al. managed to scale things up very nicely, and had seemingly good results.

CNN with grouped, sparsely connected network pathways
Course project Dec 2022 (hosted online Jul 1, 2022)

Spontaneous Decomposition from Grouped Network Pathways

Abstract

There have been many recent breakthroughs in self-supervised learning (SSL), i.e. unsupervised techniques used to obtain general purpose image features for downstream tasks. However, these methods often require large amounts of computational resources, and much is still unknown about how architectural choices affect the quality of self-supervised learned representations. There is still a lack of understanding of why compositional features spontaneously arise in previous self-supervised publications. In this work, we propose a class of models that is reminiscent of an ensemble. We show how this class of models can greatly reduce the number of parameters needed for learning robust representations in a self-supervised setting. Additionally, we show that sparsely connected network pathways spontaneously create decomposed representations.

Notes

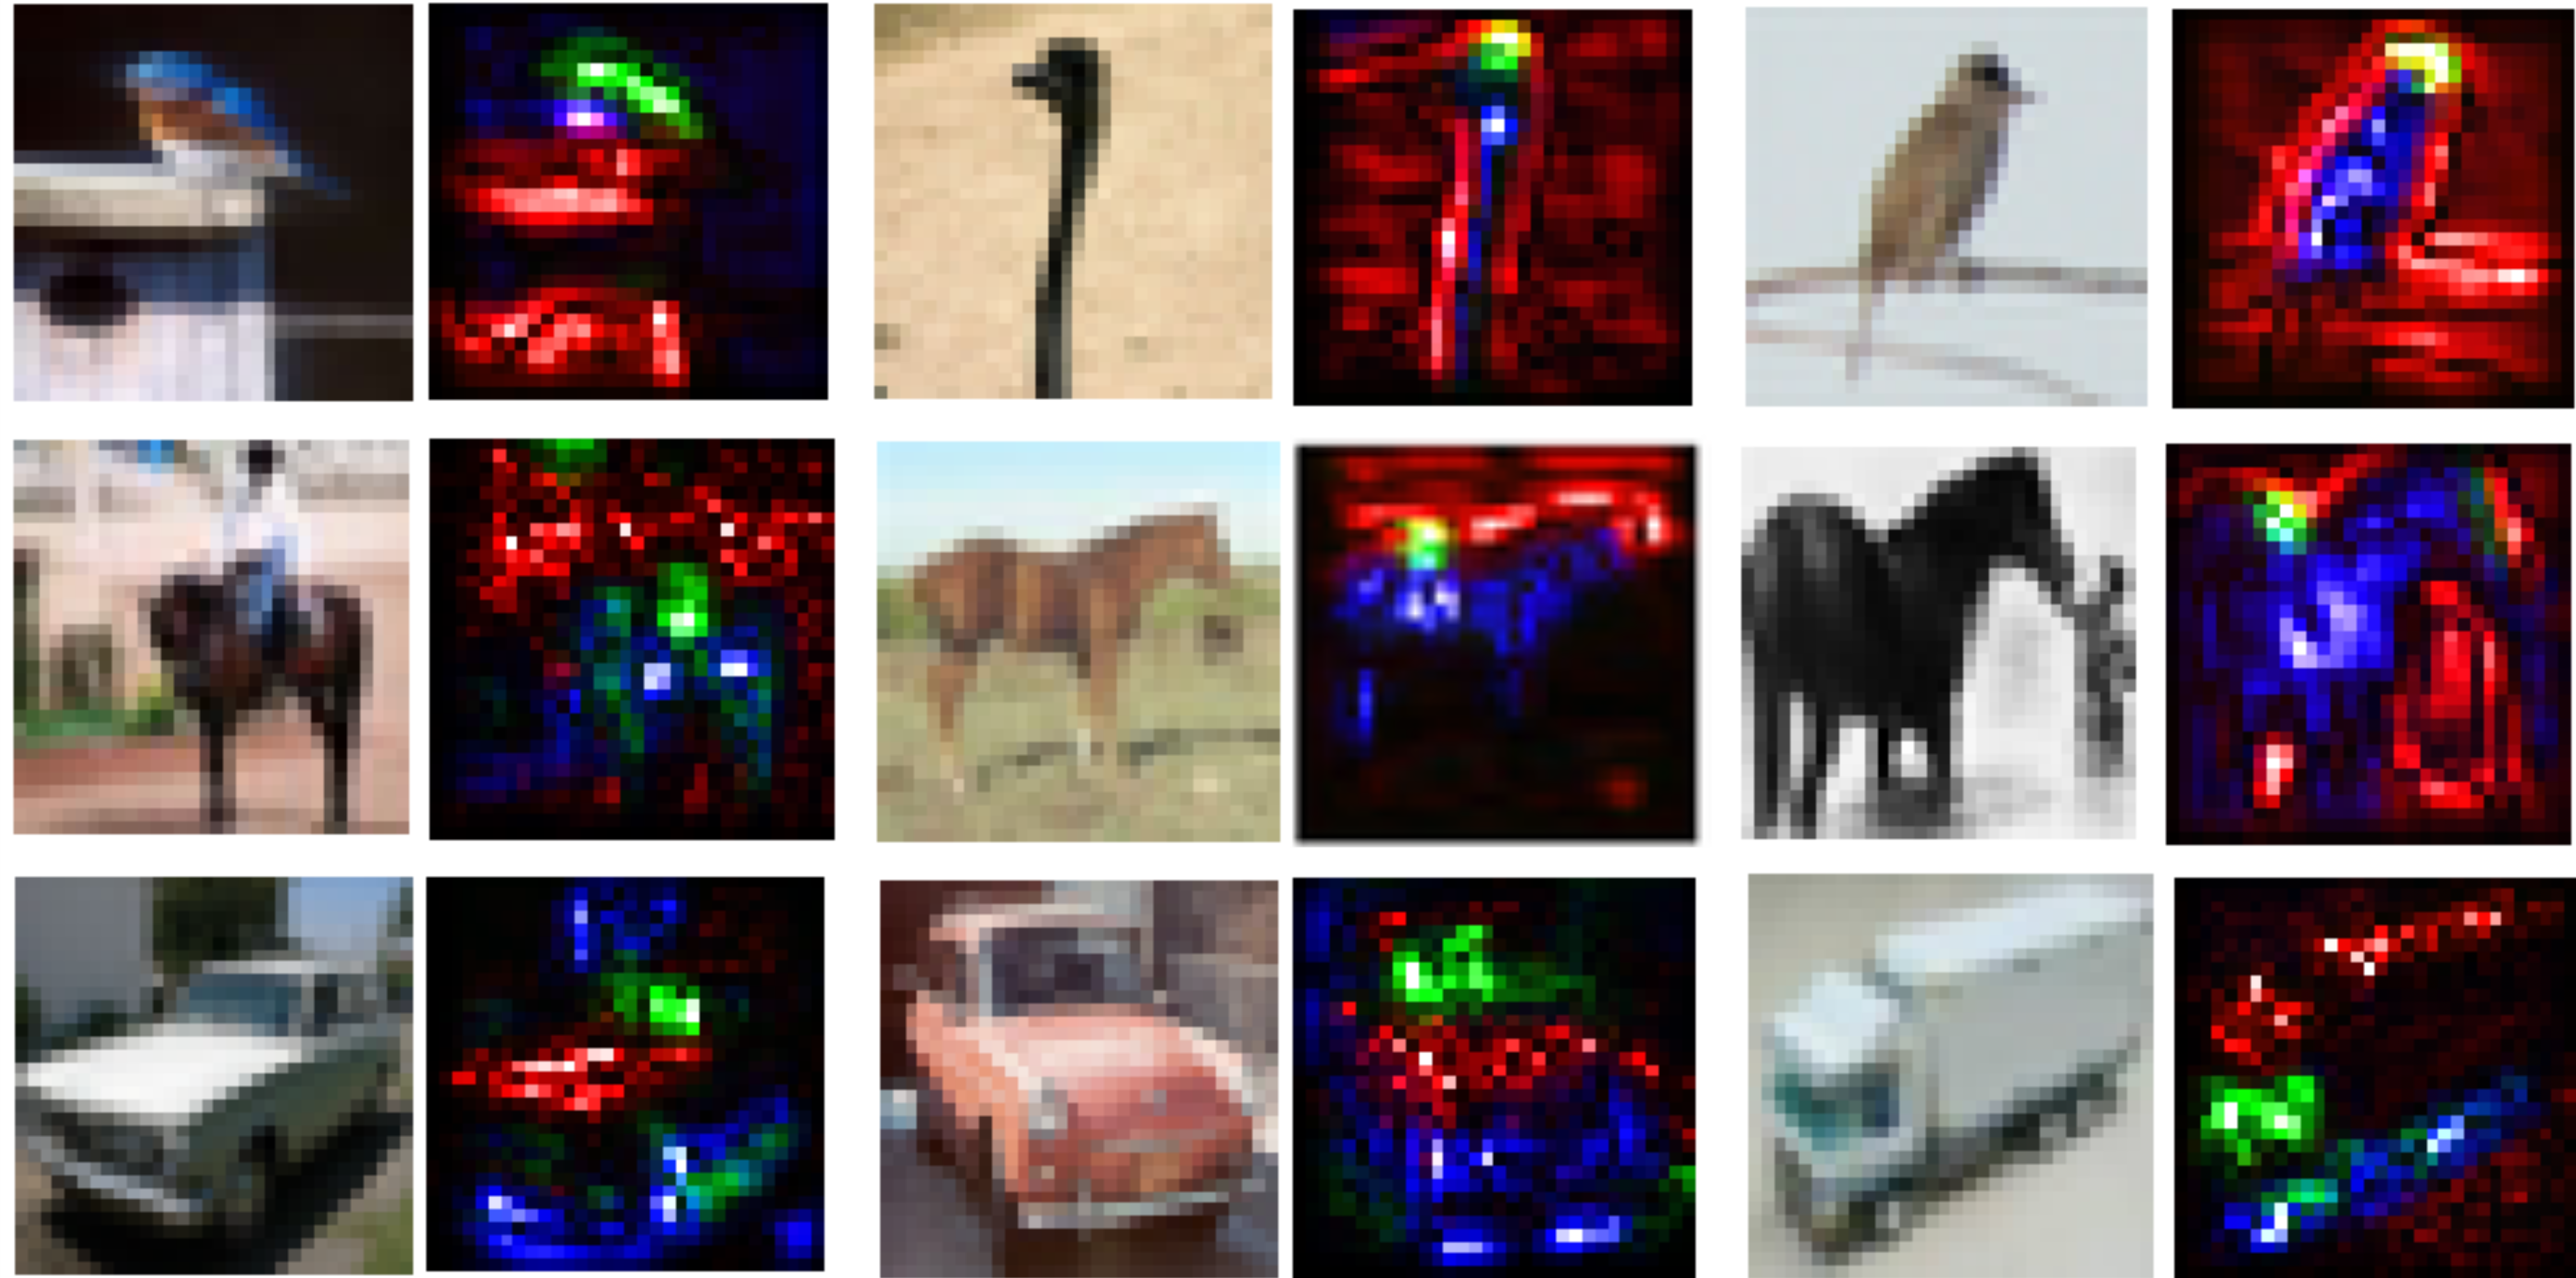
In this work, we imposed network pathway grouping on a simple CNN architecture and found that different isolated subpathways would spontaneously learn distinct features of the training data. We also showed that this grouped pathway architecture had performance benefits over vanilla variants when holding parameter counts constant. We also made a poster here. I think this work was great, but we struggled with our message and audience. It was a project for Stanford's Computer Vision course so we attempted to frame the project as an architectural contribution, validating the representations on a performance benchmark (CIFAR10 image classification). I think the project is more interesting, however, for its qualitative findings about learned representations. I still think this work has promise, but I'm not familiar with the greater literature. And since we completed this project, I think there has been some good theory work that could potentially explain our findings in terms of a Neural Race Reduction.

Chain of Shortcuts training diagram
Writeup December 6, 2023

Improving Chain of Thought with Chain of Shortcuts

Abstract

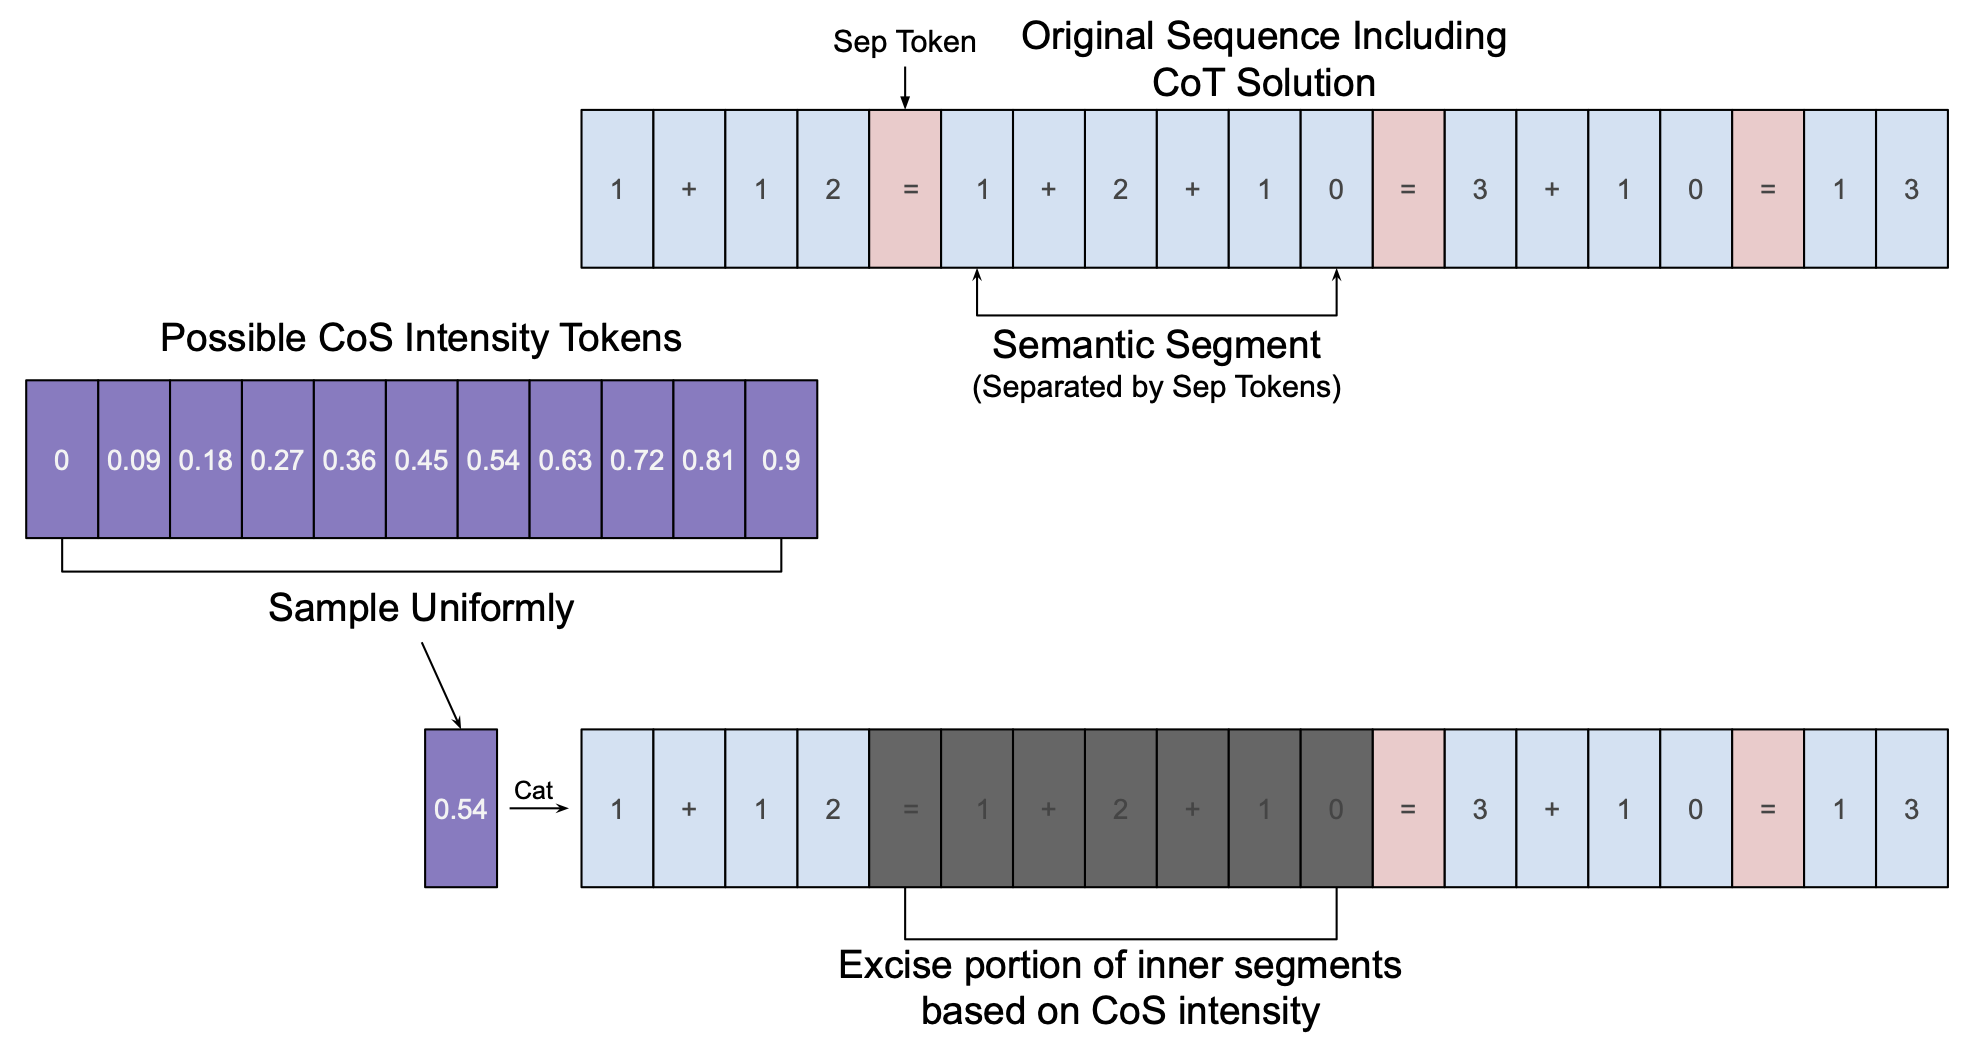
Large Language Models (LLMs) have demonstrated remarkable language modeling and sequence modeling capabilities with capabilities like In-Context Learning (ICL) and Chain of Thought (CoT) reasoning, akin to human working memory and reasoning. Drawing inspiration from dual process theory in human cognition, we propose a novel training technique called Chain of Shortcuts (CoS) that bridges the gap between LLMs’ System 1 (automatic) and System 2 (deliberate) modes. CoS enables LLMs to compress reasoning trajectories, encouraging associations between earlier and later steps in problem-solving, resulting in shorter, more flexible solutions. We demonstrate that CoS-trained language models maintain or outperform baseline models while generating distilled problem solutions, enhancing stability during training, and excelling in high-temperature environments. CoS’s effectiveness increases with the number of transformer layers until saturation. Our work not only contributes to mathematical transformers but also offers insights into human dual process theory, paving the way for more efficient and robust AI systems.

Notes

Overall, this project's direction no longer seems promising as a longterm focus 😢 Another paper called GPT Can Solve Mathematical Problems Without a Calculator came out in September that essentially does what we were moving towards in terms of a Computer Science contribution. And the cognitive focus of this work is probably too abstract to be much of a contribution. This writeup was intended to be a NeurIPS workshop submission, but due to the reasons mentioned above, combined with a misinterpretation of the workshop deadline (12AM vs 12PM 😅), it was never submitted (and probably never will be).